
Long context does not guarantee accurate change tracking, StateBench demonstrates
Researchers introduced StateBench—a benchmark for evaluating how language models track state changes of entities in long documents.
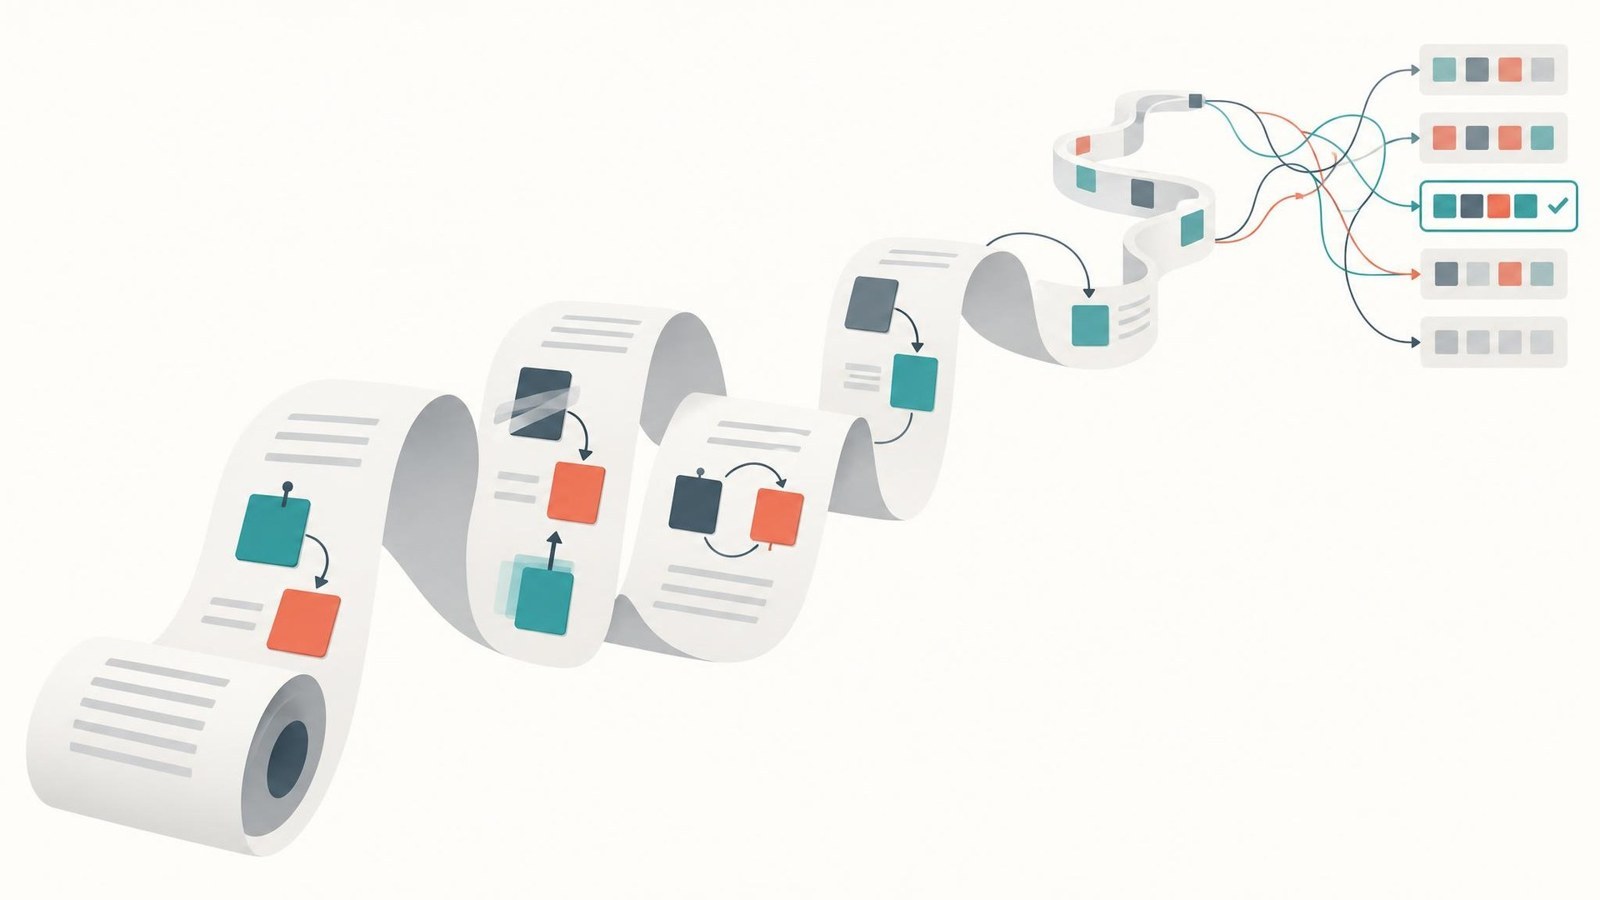
Researchers developed StateBench to assess four levels of state tracking—from finding the initial value to accounting for chains of interconnected changes. The benchmark tests tasks in multiple formats while keeping the number of variables, values, and update positions consistent.
On open models, nearly all systems performed well on simple tasks but lost accuracy on aperiodic tasks as input length increased and remained at the level of random guessing in general final-type tasks. Gemini 3.8 Flash, Claude Opus 5.5, and GPT-6 Sol and Luna showed strong results on two basic levels, but on more complex tasks, accuracy on the longest general final-type tasks dropped to 13% or lower.
When trained directly on StateBench, hybrid models and Gated DeltaNet almost flawlessly generalized results across the three simpler levels, even for the longest tested sequences—tens of thousands of assignments. Transformers mastered simple levels but performed worse on long sequences and failed to solve general final-type tasks. The authors note that the test assumes a fixed number of variables, whereas in real-world tasks, new entities may appear throughout the text.